The Complete Guide to Prompt Engineering: Techniques, Examples, and Best Practices
Learn prompt engineering from the ground up: prompt anatomy, zero-shot, few-shot, and chain-of-thought techniques, real examples, common mistakes, and best practices.
Panji Ihsanudin Fajri
13 min read1 reads
Contents
- What Is Prompt Engineering?
- Why Prompt Engineering Matters
- Dramatically better output at zero extra cost
- Consistency for production use
- Fewer hallucinations and better security awareness
- The Anatomy of a Good Prompt
- Core Prompt Engineering Techniques
- 1. Zero-shot prompting
- 2. Few-shot prompting
- 3. Chain-of-thought (CoT) prompting
- 4. Role prompting and system prompts
- 5. Structured output and delimiters
- Comparing Prompting Techniques
- Real Example: Iterating a Meeting-Summary Prompt
- Common Mistakes and How to Avoid Them
- Prompt Engineering Best Practices
- FAQ
- Is prompt engineering still relevant with newer, smarter models?
- What is the ideal prompt length?
- Are prompts in languages other than English as effective?
- What's the difference between prompt engineering and fine-tuning?
- How do you measure the quality of a prompt?
- Conclusion
You've tried an AI like ChatGPT or Claude, typed a question, and felt disappointed when the answer came back generic, off-target, or just wrong. The problem is almost never the model — it's prompt engineering, the way you phrase instructions for the language model. The same model, guided by a well-crafted prompt, can go from sloppy guesses to precise, ready-to-use output.
This is a complete guide to prompt engineering: what it is, why the skill matters, the anatomy of a good prompt, core techniques like zero-shot, few-shot, and chain-of-thought, plus real examples, common mistakes, and best practices you can apply today.
Summary: Prompt engineering is the art and science of designing instructions so that large language models (LLMs) produce accurate, relevant output. The key points: (1) a good prompt combines a role, context, clear instructions, examples, and an output format; (2) techniques like few-shot and chain-of-thought measurably improve answers on complex tasks; (3) iteration — systematically testing and refining prompts — is the key to consistent results; (4) avoid ambiguous instructions and long unstructured prompts.
What Is Prompt Engineering?
Prompt engineering is the practice of designing, testing, and refining the instructions (prompts) given to large language models so they reliably produce the desired output. The word "engineering" is deliberate: this isn't casual typing, but a systematic process of structuring input on purpose, measuring the results, and improving them iteratively.
To see why it matters, think of an LLM as a brilliant but literal assistant. It can't read your mind; it only predicts the most plausible continuation of the text you give it. A vague prompt like "write about marketing" leaves too much room for interpretation, so the result is random. A well-engineered prompt narrows that space of possibilities toward exactly what you want.
Prompt engineering operates at several layers. The most basic is ad-hoc prompting for everyday use — asking AI to summarize a document or draft an email. The next layer is systematic prompting for repeatable workflows, such as prompt templates used by a support team. The most advanced layer is system-level prompting: the system prompt that defines a production chatbot's behavior, complete with safety rules and structured output formats like JSON.
Why Prompt Engineering Matters
This skill matters not because AI is weak, but precisely because it is so powerful and flexible — and that flexibility needs direction.
Dramatically better output at zero extra cost
Research and practitioner experience show a consistent pattern: well-designed prompts can significantly improve answer accuracy without switching models or adding compute cost. Techniques like providing examples (few-shot) or asking the model to reason step by step (chain-of-thought) routinely turn wrong answers into right ones on reasoning tasks. It's a free upgrade — you're only changing the input text.
Consistency for production use
If you're building on top of LLMs — a chatbot, automatic summarization, an AI agent — you need consistent output, not output that's good "sometimes." Disciplined prompt engineering, backed by testing against a set of sample cases, is how you make model behavior stable before your code ships to production.
Fewer hallucinations and better security awareness
Clear prompts about boundaries ("answer only from the provided document; if you don't know, say so") demonstrably reduce the model's tendency to fabricate facts. Conversely, understanding how prompts work helps you recognize attacks like prompt injection, where malicious input tries to override system instructions — essential knowledge if you're building systems that accept user input.
The Anatomy of a Good Prompt
Effective prompts typically contain five components. You won't use all of them every time, but knowing each one helps you diagnose why a prompt fails.

1. Role. Giving the model a role narrows the style and perspective of its answer. "Act as a meticulous senior editor" produces a different tone than "act as a casual friend." Roles work best when specific and relevant to the task.
2. Context. This is the background information the model needs to answer well: who the audience is, what the goal is, what constraints apply. Without context, the model guesses — and its guesses are often wrong. Good context looks like: "The audience for this article is junior developers new to APIs."
3. Core instruction. A clear, specific, actionable command. Replace vague adjectives like "good" or "engaging" with concrete criteria: "write in 3 paragraphs, max 4 sentences each, in a casual tone."
4. Examples. One or two input-output examples show the model the pattern you want far more effectively than paragraphs of explanation. This is the foundation of few-shot prompting, covered below.
5. Output format. Specify the shape of the answer: a bullet list, a markdown table, JSON with specific fields, or a maximum length. This is critical for code integration, where you need parseable output.
Here's a prompt combining all of them:
Act as a senior technical writer. [role]

You're writing documentation for a payments API used by
junior backend developers. [context]

Explain webhooks in max 150 words, with one example JSON
payload. Avoid unexplained jargon. [instruction]

Format: one explanatory paragraph, then a JSON code block. [format]
Notice how much more directed this is than just "explain webhooks."
Core Prompt Engineering Techniques
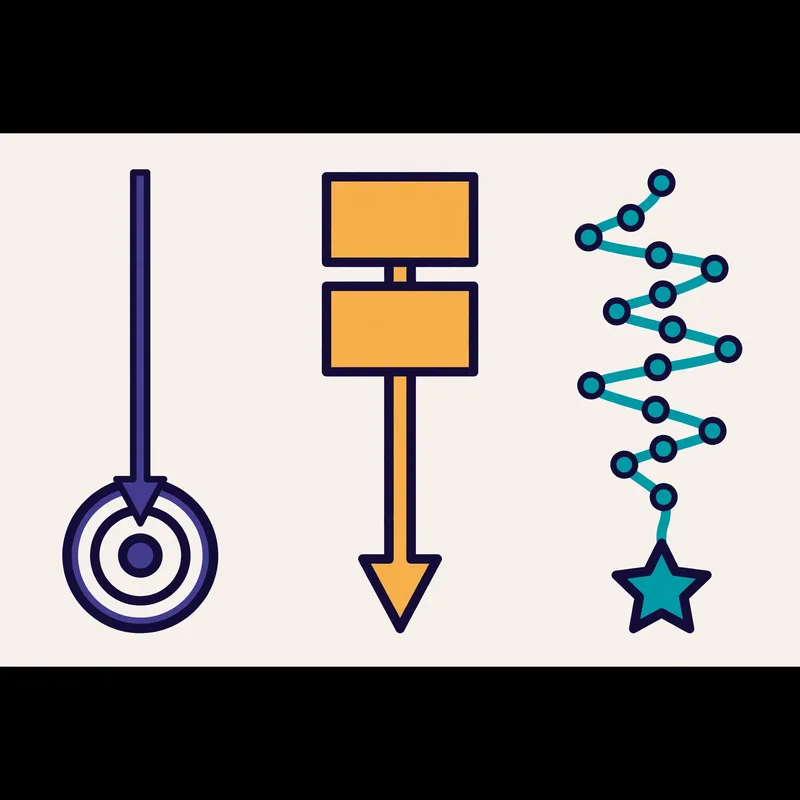
A handful of core techniques underpin nearly all modern prompt engineering practice. Master these five before exploring anything more exotic.
1. Zero-shot prompting
The simplest technique: give the instruction directly, with no examples. Modern models are strong enough to handle many tasks zero-shot, especially when the instruction is clear.
Classify the following review as positive, negative, or neutral.
Reply with a single word only.

Review: "Shipping was fast but the item arrived damaged."
Zero-shot suits tasks with clear, common definitions. Its weakness: for specific output formats or ambiguous tasks, the model often guesses.
2. Few-shot prompting
Provide 2–5 input-output example pairs before the actual task. Popularized by the GPT-3 paper ("Language Models are Few-Shot Learners"), this remains one of the most powerful ways to control output format and style.
Convert passive sentences to active voice.

Example 1:
Passive: "The report was written by the finance team."
Active: "The finance team wrote the report."

Example 2:
Passive: "The decision will be announced tomorrow."
Active: "We will announce the decision tomorrow."

Now convert:
Passive: "The bug has been fixed by the developer."
Active:
Few-shot works because the model imitates patterns from the examples — including things that are hard to describe in words, like tone, sentence length, or table formats. Practical tip: pick diverse, representative examples, and put the example most similar to your target case last.
3. Chain-of-thought (CoT) prompting
Introduced in the 2022 paper "Chain-of-Thought Prompting Elicits Reasoning in Large Language Models," this technique asks the model to spell out its reasoning steps before giving the final answer. The result: large accuracy gains on math, logic, and multi-step reasoning problems.
The simple version just adds one sentence:
A store sells 3 apples for $2. If Dito buys 12 apples, how
much should he pay? Explain your calculation step by step
before giving the final number.
The few-shot version provides worked step-by-step examples, which gives more consistent results on hard problems. Many recent models ship with built-in "reasoning" modes that essentially automate this pattern, but understanding CoT is still useful for guiding and verifying the model's thought process.
4. Role prompting and system prompts
Assigning a role up front ("you are…") sets the tone, depth, and perspective. At the application level, this becomes the system prompt — instructions injected before the user conversation starts that apply to the whole session. A good system prompt for a support chatbot covers brand identity, topic boundaries, language style, human-escalation rules, and reply formatting.
5. Structured output and delimiters
For code integration, ask for structured output. Use delimiters (like ### or triple quotes) to separate instructions from data, so the model doesn't confuse commands with content to process:
Summarize the text between the --- markers in 2 sentences.
Reply in JSON format: {"summary": "...", "keywords": [...]}

---
The long article text...
---
Many model providers now support JSON mode or "structured outputs" that guarantee syntactically valid responses — combine them with a clear schema description for best results.
Comparing Prompting Techniques
| Aspect | Zero-shot | Few-shot | Chain-of-thought |
|---|---|---|---|
| Examples needed | None | 2–5 examples | Optional (0 or a few) |
| Prompt length | Short | Medium–long | Medium–long |
| Token cost | Cheapest | More expensive | More expensive (long output) |
| Best for | Simple, common tasks | Specific formats/styles | Multi-step reasoning |
| Main weakness | Inconsistent output | Needs quality examples | Slow, token-hungry |
| When to use | Quick exploration, simple classification | Data extraction, writing style | Math, logic, debugging |
The practical rule: start with zero-shot. If results aren't consistent, move up to few-shot. If the task needs reasoning, add chain-of-thought. Don't reach for heavy techniques on light problems — every technique lengthens the prompt, which means more cost and latency.
Real Example: Iterating a Meeting-Summary Prompt
Theory without practice is useless. Here's a real-world case of how a bad prompt was improved through iteration into a reliable meeting-notes summarizer.
The initial (bad) prompt:
Summarize this meeting.
Results were inconsistent: sometimes too long, sometimes dropping key decisions, sometimes adding information that wasn't in the notes.
The prompt after 3 iteration rounds (good):
You are a meticulous executive assistant. Summarize the
meeting notes below for a manager who couldn't attend.

Rules:
- Max 200 words.
- Only use information from the notes; don't add new facts.
  If something is unclear, write "not specified".
- Format:
  1. Decisions (max 5 bullets)
  2. Action items as a table | Owner | Deadline |
  3. Unresolved topics

Notes:
---
...the meeting notes...
---

The key changes: a clear role, a word limit, an anti-hallucination rule ("don't add new facts"), and an explicit output format. Each iteration round was tested against 5–10 real meeting notes, and the final prompt became a template used by the whole team. This pattern is what separates casual AI use from professional AI integration.
Common Mistakes and How to Avoid Them
1. Prompts that are too vague. "Create a marketing strategy" with no product, audience, or budget context produces generic advice nobody can execute. Fix: always include minimal context — who, for what purpose, under what constraints.
2. Contradictory instructions. "Answer briefly but explain in detail" confuses the model. Fix: set a clear priority, e.g., "answer in 3 sentences; if detail is needed, add one optional paragraph."
3. Too many instructions in one prompt. A 500-word prompt with 15 rules makes the model "forget" some of them. Fix: split into multiple steps, or prioritize the 3–5 most important rules and test whether all are followed.
4. No output format specified. Without a format, you get a long paragraph when you needed a table for your spreadsheet. Fix: always specify the format, especially for output that feeds into code.
5. Assuming the model remembers the conversation perfectly. In long conversations, early instructions can get "buried." Fix: for important workflows, restate key constraints periodically, or summarize the context and start a fresh session with that summary.
6. Never re-testing after a model update. Model behavior changes between versions; a prompt that's perfect on one model can degrade on another. Fix: keep a set of test examples (an eval set) and re-run it whenever you switch models.
Prompt Engineering Best Practices
- Start simple; add complexity only when needed. Zero-shot first; move to few-shot or CoT when results fall short.
- Be specific about what you want, not what you don't want. "Write in a formal tone" works better than "don't be too casual."
- Use examples for things that are hard to describe. Format, style, and tone are easier to imitate from examples than to define.
- Separate instructions from data with clear delimiters. This reduces the risk of the model mixing up commands with content.
- Ask the model to acknowledge uncertainty. Phrases like "if unsure, say you don't know" measurably reduce hallucinations.
- Control decoding parameters for production. Low temperature (0–0.3) for factual, deterministic tasks; higher for creative brainstorming.
- Build an eval set before optimizing. Collect 10–20 representative examples with ideal outputs, then measure every prompt change against it.
- Document prompts like code. Keep them in version control, comment on why each rule exists, and record test results.
To go deeper, official resources like OpenAI's prompt engineering guide, Anthropic's prompt engineering docs, and the community-maintained Prompting Guide are continuously updated as models evolve.
FAQ
Is prompt engineering still relevant with newer, smarter models?
Yes, but its shape is shifting. Newer models follow simple instructions better, so elaborate tricks needed for older models are less necessary. Yet deeper needs are growing: designing system prompts for production apps, building evaluations, handling security issues like prompt injection, and orchestrating many prompts inside AI agents. The skill is leveling up, not disappearing.
What is the ideal prompt length?
There's no magic number — what matters is the signal-to-noise ratio. A dense, specific 50-word prompt beats a rambling 500-word one. For production apps, measure: add context while your eval metrics improve, and stop when results plateau, since extra tokens only add cost.
Are prompts in languages other than English as effective?
Large models are generally strongest in English because it dominates their training data, but modern models are highly capable in many other languages for most tasks. For complex or nuanced instructions, writing the prompt in English while requesting output in your target language is often the best hybrid strategy.
What's the difference between prompt engineering and fine-tuning?
Prompt engineering changes the input at inference time without touching model weights — fast, cheap, and changeable anytime. Fine-tuning retrains (part of) the model's weights on a custom dataset — more expensive and permanent, but useful for teaching styles, domains, or behaviors that prompts can't reliably achieve. Best practice: max out prompting first, and fine-tune only when prompting provably falls short.
How do you measure the quality of a prompt?
Build an eval set: 10–30 sample inputs with correct-output criteria (exact answers, checklists, or rubric scoring). Run the prompt against this set and score it. Every prompt change must be re-tested — without measurement, prompt "improvements" are just hunches and often make things worse.
Conclusion
Prompt engineering is a core skill of the AI era: the ability to design instructions that turn a language model from a random answer machine into a precise, reliable tool. Start with the fundamentals — understand the anatomy of a good prompt, master zero-shot, few-shot, and chain-of-thought, then build the habit of iterating prompts with systematic testing rather than gut feeling.
A concrete next step: take one recurring task from your work this week — summarizing emails, writing reports, classifying data — and apply the patterns from this guide. Write the first prompt version, test it on 5 real examples, refine it, and save it as a template. You'll feel the difference yourself.
Good prompts aren't talent; they're a trainable discipline. And like every engineering discipline, they improve every time you measure the results.